
Introduction
In this blog, I am going to describe various reasons behind the Big-Data explosion and will be giving a detailed view and solutions about
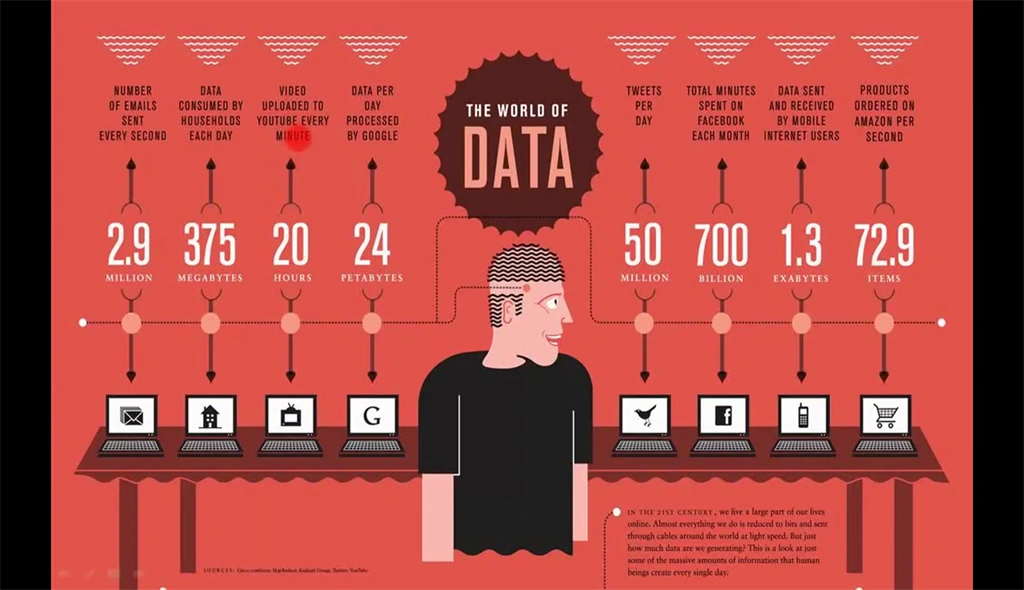
The Data Explosion
There are 2.5 quintillion bytes of data created each day. The data growth is growing at a 40 percent compound annual rate, reaching nearly 45 zettabyte by 2020.
The essence of Big-data
- Volume(Data at Rest)-Terabytes to exabytes of existing data to process
- Velocity(Data in Motion)-Streaming data, milliseconds to seconds to respond
- Variety(Data in Many forms)-structured, unstructured, text , multimedia etc..,
- Veracity(Data in Doubt)-Uncertainty due to data inconsistency & incompleteness , ambiguities , latency , deception , model approximations.
Examples of Big data
- 200 million weekly customers across 10,700 stores in 27 countries.
- 1.5 million customer transactions every hour
- 3 pentaBytes (PB) of data are stored in walmart’s Hadoop cluster
- Conventional Approaches:(DATA WAREHOUSE)
- For storage they use the RDBMS (oracle , DB2 ,MySQL ,etc) and OS Filesystem
- For processing it provides SQL Queries and works on the custom Framework designed by c , c++, python and perl.
CONVENTIONAL APPORACHES PROVIDES like DATA WAREHOUSE
- LIMITED STORAGE CAPACITY
- LIMITED PROCESSING CAPACITY
- NO SCALABILITY
- SINGLE POINT OF FAILURE
- SEQUENTIAL PROCESSING
- RDBMSs can handle structured data
- REQUIRES PREPROCESSING OF DATA
- INFORMATION IS COLLECTED ACCORDING TO CURRENT BUSINESS NEEDS.
THE SOLUTION TO BIG-DATA AND HADOOP
Hadoop
An open source project from Apache Software Foundation. It provides a software framework for distributing and running applications on clusters of servers that is inspired by Google’s Map-Reduce programming model as well as its file system(GFS).Hadoop was originally written for the nutch search engine project.
Hadoop is open source framework written in Java. It efficiently processes large volumes of data on a cluster of commodity hardware. Hadoop can be setup on single machine , but the real power of Hadoop comes with a cluster of machines , it can be scaled from a single machine to thousands of nodes.
Hadoop consists of two key parts,
- Hadoop Distributes File System(HDFS)
- Map-Reduce.
Hadoop Distributed File System(HDFS)
HDFS is a highly fault tolerant, distributed, reliable, scalable file system for data storage. HDFS stores multiple copies of data on different nodes; a file is split up into blocks (Default 64 MB) and stored across multiple machines. Hadoop cluster typically has a single namenode and number of datanodes to form the HDFS cluster.
Map-Reduce
Map-Reduce is a programming model designed for processing large volumes of data in parallel by dividing the work into a set of independent tasks. It is also a paradigm for distributed processing of large data set over a cluster of nodes.
Why Hadoop & Big-Data Analysis
There is a huge competition in the market that leads to the various customers like,
- Retail-customer analytics (predictive analysis)
- Travel-travel pattern of the customer
- Website-understand various user requirements or navigation pattern , interest , conversion etc..,
- Sensors , satellite , geospatial data that are used for research purposes that need to be stored.
- Military and intelligence also needs to store the large amount of data for various purpose with security.
Hadoop Use-cases
- Turn 12 Terabytes of tweets created each day into improved product sentiment analysis.
- Turn billions of customer complaints to analyze root cause of customer churn
- Analyze customer’s searching / buying pattern and show them advertisement of attractive offers in real time.
- Millions credit card transaction done each day-identify potential fraud.
Summary
I hope that you have understood the various reasons for Data Explosion and also the need of Hadoop to solve the Big-Data problem.
Hadshana KamalanathanPosted Jul 19, 2018, 12:37 AM
Thanks for sharing
Reshwanth SPosted Sep 18, 2017, 1:01 PM
Good article dude very nice