
Suppose we have many records in a table and some of them are duplicate records. So it is necessary to delete all duplicate records from the table as per our business requirement.
Here, I am creating a sample table and inserting some junk data for deleting duplicate rows.
Below is the script for creating a sample table.
- CREATE TABLE Student
- (
- Id int IDENTITY(1,1) NOT NULL,
- Name varchar(50) NOT NULL,
- Class varchar(50) NULL,
- FatherName varchar(50) NULL,
- )
- INSERT INTO Student(Name, Class, FatherName)
- VALUES
- ('student1', 'one', 'father1'),
- ('student1', 'one', 'father1'),
- ('student2', 'two', 'father2'),
- ('student3', 'three', 'father3'),
- ('student3', 'three', 'father3'),
- ('student3', 'three', 'father3'),
- ('student4', 'four', 'father4');
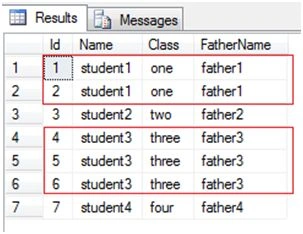
Here, there are some duplicate records present into the Student table.
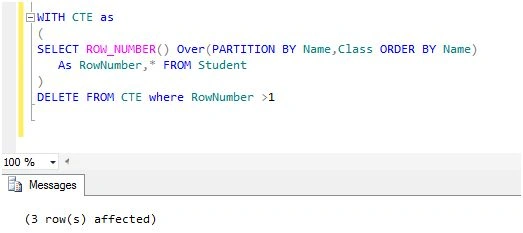
So now we are deleting duplicate rows by using Common Table Expression (CTE) and ROW_NUMBER().
Below is the script for the same.
- WITH CTE as
- (
- SELECT ROW_NUMBER() Over(PARTITION BY Name,Class ORDER BY Name)
- As RowNumber,* FROM Student
- )
- DELETE FROM CTE where RowNumber >1
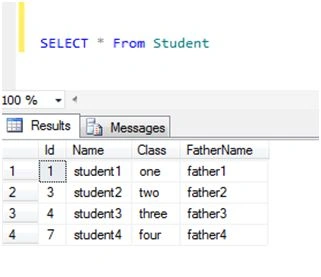
Now using select query to see records into the Student table.
- SELECT * From Student
SubashPosted Aug 22, 2016, 12:51 AM
Good share
Gajanan ShindePosted Apr 16, 2016, 3:48 AM
Nice share...
Sandeep KumarPosted Mar 31, 2016, 1:38 PM
Good one