
Introduction
Natural Language Processing (NLP) is a critical area of artificial intelligence that focuses on the interaction between computers and human language. One of the fundamental tasks in NLP is text normalization, which involves converting text into a standard format. Two key techniques for text normalization are stemming and lemmatization. Both methods aim to reduce words to their base or root form, making text easier to analyze.
What is Stemming?
Stemming is a text normalization technique that involves chopping off the ends of words to reduce them to their base or root forms, often without considering the actual meaning of the word. This process is crude and can sometimes lead to incorrect or non-existent words.
Common Stemming Algorithms
- Porter Stemmer: One of the most widely used stemming algorithms, known for its simplicity and speed.
- Snowball Stemmer: An improvement over the Porter Stemmer, supporting multiple languages.
- Lancaster Stemmer: An aggressive stemming algorithm that produces shorter stems.
Applications of Stemming
- Speed-Critical Applications: Search engines where quick indexing is needed.
- Tolerance to Minor Inaccuracies: Applications where slight deviations in word forms are acceptable.
Limitations of Stemming
- Over-Stemming: E.g., "running" to "run", which can lead to loss of meaning.
- Under-Stemming: E.g., "happiness" to "happi", which may not be useful.
How does stemming work?
Stemming is a text normalization technique that reduces words to their base or root forms by removing suffixes and prefixes. This process uses a set of rules to chop off these parts of the word, often without considering whether the resulting form is a valid word in the language. Stemming can be useful in applications where exact word forms are less important than capturing the core meaning of words quickly.
Example
pip install nltk
from nltk.stem import PorterStemmer
stemmer = PorterStemmer()
# Sample words
words = ["running", "runner", "ran", "runs"]
# Apply stemming
stems = [stemmer.stem(word) for word in words]
print(stems)
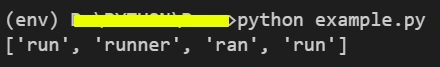
Output
Explanation
In the above code, first, we need to install nltk library.
- "running" becomes "run": The suffix "-ing" is removed.
- "runner" remains "runner": The algorithm determines that further stemming is not beneficial.
- "ran" remains "ran": The word is already in its base form.
- "runs" becomes "run": The suffix "-s" is removed.
The Porter Stemmer applies a series of rules to each word, iterating through steps to transform the word to its stem. For example, it first checks for plurals, then for various common suffixes.
What is Lemmatization?
Lemmatization is a more sophisticated text normalization technique that reduces words to their base or dictionary form, known as the lemma. Unlike stemming, lemmatization takes into account the morphological analysis of the words, ensuring that the base form is a valid word in the language.
Key Tools for Lemmatization
- WordNet Lemmatizer (NLTK): Uses the WordNet database to find the lemma of a word.
- SpaCy Lemmatizer: A powerful library for NLP tasks that includes a built-in lemmatizer.
- Stanford CoreNLP Lemmatizer: A comprehensive NLP toolkit that offers lemmatization.
Applications of Lemmatization
- High Accuracy Requirements: Sentiment analysis where preserving word meaning is crucial.
- Human Language Processing: Contexts requiring text to be close to natural human language.
Limitations of Lemmatization
- Vocabulary Dependency: Requires a comprehensive dictionary and context understanding.
- Slower Processing Time: Due to the complexity of morphological analysis.
How does Lemmatization work?
Example
pip install nltk
import nltk
from nltk.stem import WordNetLemmatizer
# Initialize the lemmatizer
lemmatizer = WordNetLemmatizer()
words = ["running", "runner", "ran", "runs"]
# Apply lemmatization
lemmas = [lemmatizer.lemmatize(word, pos='v') for word in words]
print(lemmas)
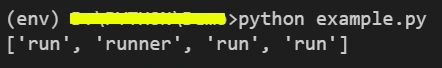
Output
Explanation
- "running" becomes "run": The lemmatizer uses the verb form "running" and returns "run".
- "runner" becomes "runner": The lemmatizer recognizes "runner" as a noun, and it doesn't change with 'v' as the part of speech.
- "ran" becomes "run": The lemmatizer converts the past tense "ran" to its base form "run".
- "runs" becomes "run": The plural verb "runs" is converted to its singular base form "run".
Lemmatization uses the WordNet database to find the base forms of words, which involves looking up the word in a predefined dictionary and applying morphological rules. This ensures that the output is a valid word in the language.
Future Trends and Developments
- Advances in Algorithms: Research into more efficient and accurate stemming and lemmatization techniques.
- Integration with AI: Leveraging deep learning models for better context-aware text normalization.
- Impact on NLP Applications: Improved preprocessing leads to better performance in tasks like machine translation, sentiment analysis, and information retrieval.
Comparative example of Stemming & Lemmatization
Let's compare the outputs of stemming and lemmatization for the same set of words.
Example
from nltk.stem import PorterStemmer
from nltk.stem import WordNetLemmatizer
# Initialize the stemmer and lemmatizer
stemmer = PorterStemmer()
lemmatizer = WordNetLemmatizer()
# Sample words
words = ["better", "best", "running", "runners", "ran", "runs"]
# Apply stemming
stems = [stemmer.stem(word) for word in words]
print("Stemming:", stems)
# Apply lemmatization
lemmas = [lemmatizer.lemmatize(word, pos='a') if word in ["better", "best"] else lemmatizer.lemmatize(word, pos='v') for word in words]
print("Lemmatization:", lemmas)
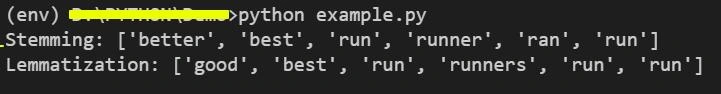
Output
Explanation
- "better" and "best": Stemming leaves these words unchanged, while lemmatization recognizes "better" as the comparative form of "good".
- "running": Both techniques reduce this to "run", though stemming does so by chopping off "-ing", and lemmatization does so by morphological analysis.
- "runners": Stemming leaves "runner" mostly intact, while in lemmatization, it stays the same as it's not a verb.
- "ran": Stemming leaves it unchanged, while lemmatization converts it to its base form "run".
- "runs": Both techniques reduce this to "run".
By comparing these outputs, we can see that stemming is simpler and faster but less accurate, whereas lemmatization is more precise and retains meaningful base forms, making it suitable for applications requiring high accuracy.
Conclusion
Stemming and lemmatization are essential techniques in NLP, each with its own strengths and suitable applications. Stemming is fast and simple, making it ideal for applications where speed is critical. Lemmatization, on the other hand, provides more accurate and meaningful base forms, which is crucial for tasks that require high precision.
Choosing the right technique depends on the specific needs of the application. Understanding the differences and appropriate use cases for each can significantly enhance the effectiveness of NLP systems.
Join the conversation! Your thoughts help the community grow.