
Introduction
Large Language Models (LLMs) have revolutionized AI-driven applications, from chatbots to code generation. However, their computational demands pose significant challenges, particularly in real-time inference. Azure AI Supercomputing Clusters provide the necessary infrastructure to optimize LLM inference, ensuring faster, cost-effective, and scalable AI deployments. This article explores how to leverage Azure’s AI supercomputing capabilities for efficient LLM inference.
The Challenge of LLM Inference
LLMs, such as GPT-based models, require extensive computing resources due to,
- High computational overhead: Processing complex queries necessitates vast parallel processing.
- Memory bottlenecks: Handling large parameter models demands efficient memory distribution.
- Latency constraints: Applications such as chatbots and automated assistants need real-time responses.
- Scalability limitations: Scaling inference across multiple nodes introduces synchronization challenges.
To address these challenges, Azure AI Supercomputing Clusters offer specialized infrastructure designed to optimize LLM inference.
Leveraging Azure AI Supercomputing Clusters
Azure AI Supercomputing Clusters provide a robust ecosystem for deploying and optimizing LLM inference through a combination of cutting-edge hardware and software solutions.
1. GPU-Accelerated Inference
Azure integrates powerful GPUs, including NVIDIA A100 and H100 Tensor Core GPUs, to accelerate deep learning workloads. Using GPU parallelism, model inference time is drastically reduced. Key features include.
- Tensor cores for optimized matrix operations
- Multi-GPU scaling for distributed inference
- High-bandwidth memory (HBM) for efficient data access
2. Model Parallelism and Optimization Techniques
Azure AI offers model parallelism strategies, enabling efficient inference on massive models.
- Tensor Parallelism: Splits model layers across multiple GPUs, reducing memory overhead.
- Pipeline Parallelism: Distributes computation across sequential layers for improved utilization.
- Mixture of Experts (MoE): Activates only relevant portions of the model during inference, optimizing compute usage.
3. Azure Machine Learning Managed Endpoints
Managed endpoints allow seamless deployment of LLMs with built-in auto-scaling and monitoring. Features include.
- Automatic scaling to adjust resources based on traffic load.
- Logging and monitoring for performance analysis.
- Model versioning and rollback to manage different inference models.
4. Azure Kubernetes Service (AKS) for Scalable Deployment
Azure AI supercomputing clusters integrate with AKS for containerized inference workflows. Benefits include.
- Containerized deployments using TensorFlow Serving or Triton Inference Server.
- Dynamic scaling based on workload demand.
- Seamless integration with Azure AI services and APIs.
Implementing LLM Inference Optimization
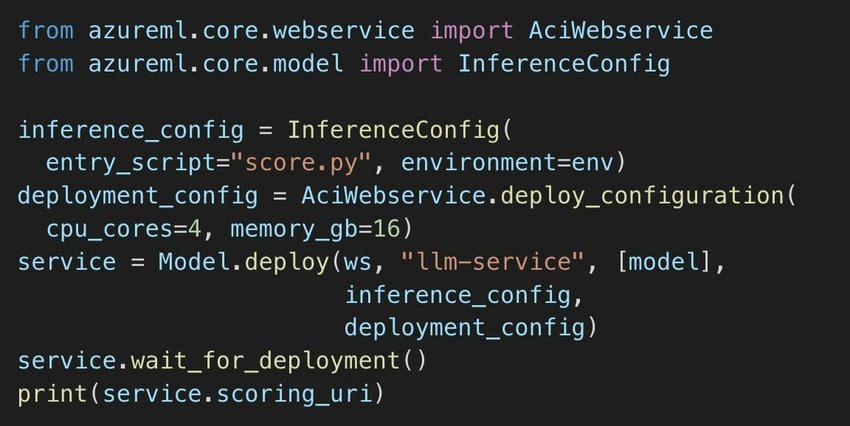
To optimize LLM inference using Azure AI Supercomputing Clusters, follow these steps.
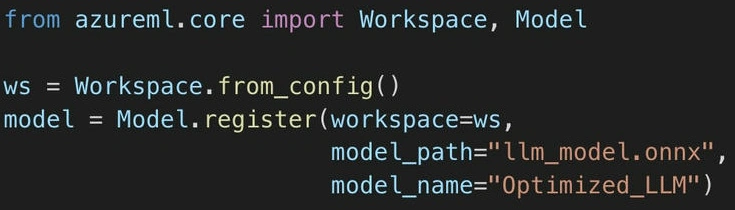
Step 1. Deploy Model on Azure Machine Learning.
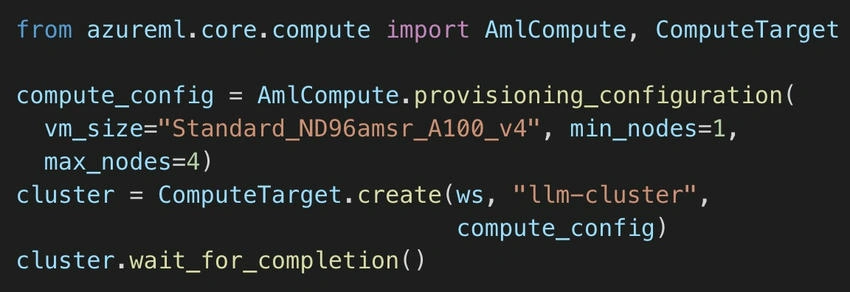
Step 2. Create an Inference Cluster.
Step 3. Deploy and Optimize the Inference Endpoint.
Best Practices for LLM Inference Optimization
- Use mixed-precision training and inference to balance accuracy and performance.
- Leverage model quantization (e.g., ONNX Runtime) to reduce memory footprint.
- Implement caching strategies to minimize redundant computations.
- Optimize batch size to achieve the best trade-off between latency and throughput.
- Monitor GPU utilization and adjust inference workload distribution accordingly.
Conclusion
Azure AI Supercomputing Clusters offer a powerful solution for optimizing LLM inference, addressing key challenges such as latency, scalability, and computational efficiency. By leveraging GPU acceleration, model parallelism, and managed inference endpoints, businesses can deploy high-performance AI applications at scale. As LLMs continue to evolve, Azure’s AI infrastructure ensures enterprises can meet the growing demand for efficient, scalable, and cost-effective AI inference.
Further Learning
Join the conversation! Your thoughts help the community grow.