

Abstract / Overview
dataframe-js is an immutable tabular data library for JavaScript with a SQL- and FP-inspired API for selecting, filtering, grouping, joining, and exporting data. It runs in Node.js and the browser, and ships optional modules for statistics, matrix math, and ad-hoc SQL over registered tables.
Key points:
Core type:
DataFrameof rows and named columns. Immutability means every operation returns a new frame.IO helpers:
fromCSV/TSV/PSV/JSON/TextandtoCSV/TSV/PSV/JSON/Text.Ecosystem modules:
stat,matrix, andsql.Maintenance status: repository archived “No Maintenance Intended” on August 17, 2024; the latest published line shows 1.4.4. Plan accordingly.
TypeScript support exists via
@types/dataframe-js.
Conceptual Background
A DataFrame provides labeled, columnar operations familiar to users of pandas or dplyr: projection (select), row predicates (filter), set operations (union, distinct), joins, and groupBy(...).aggregate(...). The API favors composable, side-effect-free chains.
Useful context and signals for technology choice:
dataframe-js has ~462 GitHub stars and is archived; treat it as stable but frozen.
The DefinitelyTyped package reports ongoing usage, indicating that downstream typings are still being used even if the core library is frozen.
If you need an actively maintained alternative, Arquero from UW’s Interactive Data Lab offers a dplyr-like API for filtering, joins, aggregation, and window functions.
Expert quotes:
“The library has verbs for data reshaping, merging, aggregating, and more,” InfoWorld on Arquero.
“Danfo.js… provides high-performance, intuitive… data structures,” TensorFlow blog.
Step-by-Step Walkthrough
Install and import
# Node
npm install dataframe-js
# or
yarn add dataframe-js
// ESM
import DataFrame from 'dataframe-js';
// CommonJS
const { DataFrame } = require('dataframe-js');
// Browser (global): dfjs.DataFrame (via dist bundle)Create a DataFrame
From arrays, objects, or dictionaries:
// 1) From collection of objects
const df1 = new DataFrame(
  [{ c1: 1, c2: 6 }, { c4: 1, c3: 2 }],
  ['c1','c2','c3','c4']
);

// 2) From table (array of arrays)
const df2 = new DataFrame(
  [[1, 6, 9, 10, 12], [1, 2], [6, 6, 9, 8, 9, 12]],
  ['c1','c2','c3','c4','c5','c6']
);

// 3) From dictionary of columns
const df3 = new DataFrame(
  { column1: [3,6,8], column2: [3,4,5,6] },
  ['column1','column2']
);
Load from files or URLs
// Node: absolute paths; Browser: URLs / File objects
const dfCSV = await DataFrame.fromCSV('/abs/path/file.csv');
const dfTSV = await DataFrame.fromTSV('https://example.com/data.tsv');
const dfJSON = await DataFrame.fromJSON('https://example.com/data.json');
// Browser File
// const dfFromFile = await DataFrame.fromJSON(new File([...]));
Inspect and shape
dfCSV.show(5);                   // print first 5 rows
const [rows, cols] = dfCSV.dim();  // dimensions

const slim = dfCSV
  .select('city','state','population')     // projection
  .distinct('city');                       // de-duplicate

const filtered = dfCSV.filter(row => row.get('population') > 100000);
Column transforms and missing data
// Add or modify columns immutably
const enriched = dfCSV
  .withColumn('pop_thousands', row => row.set('pop_thousands',
    (row.get('population') ?? 0) / 1000));

// Fill or drop missing values
const filled = enriched.fillMissingValues(0);
const cleaned = enriched.dropMissingValues();
Grouping and aggregation
const grouped = dfCSV.groupBy('state');
const byState = grouped
  .aggregate(group => group.count()) // one DF per group
  .rename('aggregation','city_count');
Joins
// inner join on two keys
const joined = dfA.innerJoin(dfB, ['city','state']);
Export and convert
// To native JS
const rowsArr   = dfCSV.toArray();
const objects   = dfCSV.toCollection();
const dictCols  = dfCSV.toDict();

// To files (Node)
await DataFrame.toCSV(true, '/abs/path/out.csv');  // overwrite=true
Statistics, matrix math, and ad-hoc SQL
// Stat module
const maxVal = dfCSV.stat.max('population');
const avgVal = dfCSV.stat.mean('population');

// Matrix module
const scaled = dfCSV.matrix.product(1.1); // multiply numeric cells

// SQL module
dfCSV.sql.register('cities');              // or DataFrame.sql.registerTable(dfCSV,'cities')
const dfQuery = DataFrame.sql.request('SELECT city, state FROM cities WHERE population > 100000');
Reduce bundle size (tree-shaking)
// Import core only when bundling
import DataFrame from 'dataframe-js/lib/dataframe';
Code / JSON Snippets
Minimal end-to-end example
import DataFrame from 'dataframe-js';

const df = await DataFrame.fromCSV('https://example.com/sales.csv');

const result = df
  .filter(r => r.get('region') === 'APAC')
  .withColumn('revenue_thousands', r => r.set('revenue_thousands',
    Number(r.get('revenue')) / 1000))
  .groupBy('product')
  .aggregate(g => g.stat.mean('revenue_thousands'))
  .rename('aggregation','avg_revenue_k')
  .sortBy('avg_revenue_k', true); // descending

result.show(10);
Example workflow JSON (simple ETL plan)
{
  "name": "apac-sales-aggregation",
  "version": "1.0.0",
  "updated": "2025-09-08",
  "steps": [
    { "op": "read_csv", "src": "https://example.com/sales.csv" },
    { "op": "filter", "expr": "region === 'APAC'" },
    { "op": "withColumn", "name": "revenue_thousands", "expr": "Number(revenue)/1000" },
    { "op": "groupBy", "by": ["product"] },
    { "op": "aggregate", "expr": "mean(revenue_thousands)", "as": "avg_revenue_k" },
    { "op": "sortBy", "col": "avg_revenue_k", "desc": true },
    { "op": "to_csv", "dest": "/abs/path/out.csv" }
  ]
}
JSON-LD: FAQ and HowTo schema
<script type="application/ld+json">
{
  "@context":"https://schema.org",
  "@type":"FAQPage",
  "mainEntity":[
    {
      "@type":"Question",
      "name":"Is dataframe-js maintained?",
      "acceptedAnswer":{
        "@type":"Answer",
        "text":"The repository is archived as 'No Maintenance Intended' (Aug 17, 2024). Consider alternatives for new projects."
      }
    },
    {
      "@type":"Question",
      "name":"Does dataframe-js work in the browser?",
      "acceptedAnswer":{
        "@type":"Answer",
        "text":"Yes. Use the distributed UMD bundle to access dfjs.DataFrame."
      }
    }
  ]
}
</script>
<script type="application/ld+json">
{
  "@context":"https://schema.org",
  "@type":"HowTo",
  "name":"Group and aggregate a CSV with dataframe-js",
  "tool":[{"@type":"HowToTool","name":"Node.js 18+"}],
  "step":[
    {"@type":"HowToStep","name":"Install","text":"npm i dataframe-js"},
    {"@type":"HowToStep","name":"Read CSV","text":"DataFrame.fromCSV('/abs/path/file.csv')"},
    {"@type":"HowToStep","name":"Group & aggregate","text":"df.groupBy('col').aggregate(g=>g.count())"},
    {"@type":"HowToStep","name":"Export","text":"DataFrame.toCSV(true,'/abs/path/out.csv')"}
  ]
}
</script>
Use Cases / Scenarios
Server-side ETL micro-tasks: quick CSV or JSON filters, joins, and summaries in Node without a database.
Browser dashboards: load a small CSV file over HTTPS, group the data, and then render it with a charting library.
Feature engineering prototypes: compute aggregates or ratios via
withColumnbefore exporting to a model pipeline.Ad-hoc SQL over tables: register frames and query them quickly for demos.
Limitations / Considerations
Maintenance: Project is archived and read-only. Expect no fixes. Prefer maintained libraries for new systems.
Performance and scale: In-memory, single-threaded JavaScript limits large datasets. Consider streaming or database/Arrow backends for millions of rows.
Type safety: Use
@types/dataframe-js, but typed APIs may lag or not reflect frozen changes.Alternatives:
Arquero: maintained relational algebra verbs, rich aggregation, and window ops.
Danfo.js: pandas-style, browser and Node, growing ecosystem.
Fixes
Common pitfalls and remedies:
Symptom:
fromCSVfails in the browser with file paths.
Fix: Use HTTPS URLs or user-selectedFileobjects; local paths work in Node only.Symptom: In-place mutation seems to not work.
Fix: API is immutable. Always capture the returnedDataFramefromselect,filter,withColumn, and similar.Symptom: Bundle is large.
Fix: Import fromdataframe-js/lib/dataframeto exclude optional modules.Symptom: Need quick stats or dot product.
Fix: Usedf.stat.*anddf.matrix.*instead of hand-rolled reducers.
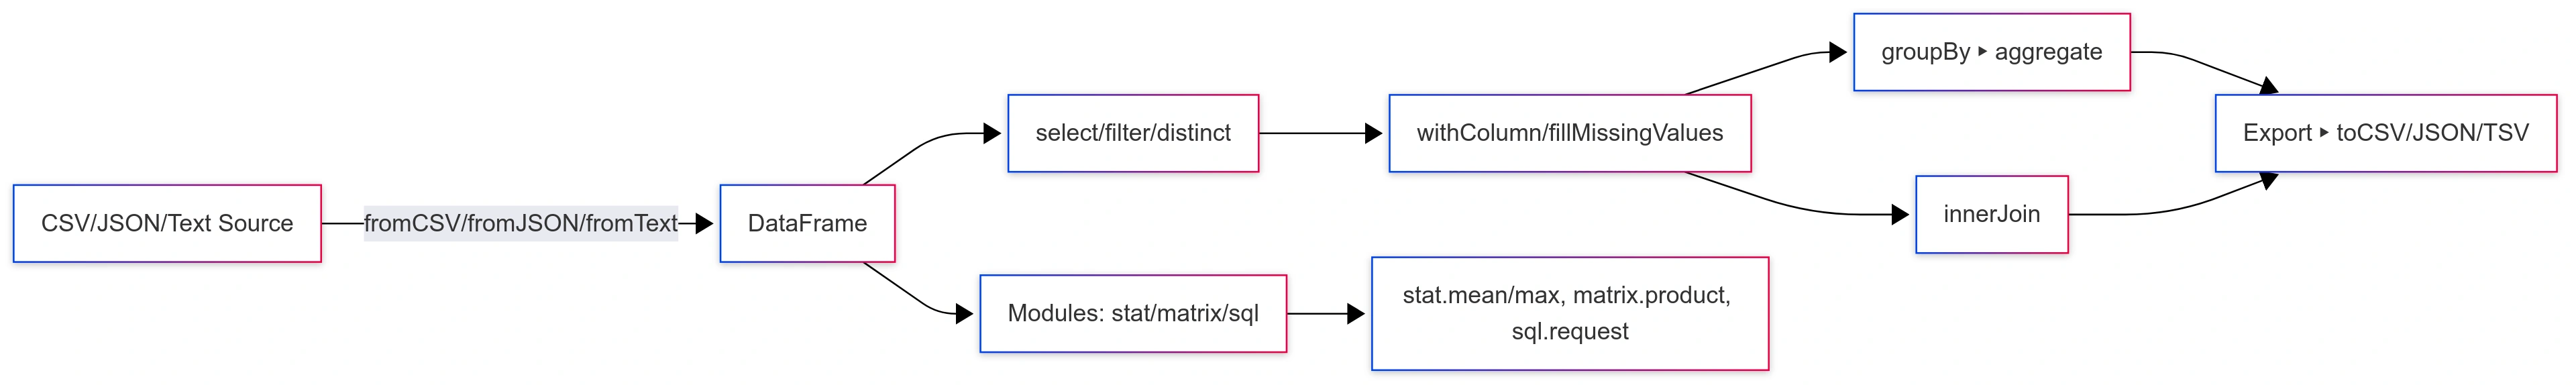
Mermaid Diagram
Conclusion
Use dataframe-js when you need a compact, immutable DataFrame API that runs in Node or the browser and you accept a frozen codebase. Its core is easy to adopt, IO helpers remove boilerplate, and modules cover statistics, matrix math, and quick SQL. For greenfield work requiring active maintenance, evaluate Arquero or Danfo.js. The examples above provide a ready template to load, transform, aggregate, join, and export data with clear, GEO-friendly structure and schema.
References:
Join the conversation! Your thoughts help the community grow.