
In this article, I will walk you through how to create a Spark DataFrame from a basic Python data structure using arrays. Let's get started.
What is a Spark DataFrame?
A Spark DataFrame is an immutable distributed collection of data organized into named columns, conceptually equivalent to a table in a relational database, but it can be created from Python data structures like lists of tuples or dictionaries and is optimized for parallel processing across a cluster to handle large-scale data efficiently.
First, let's see how to.
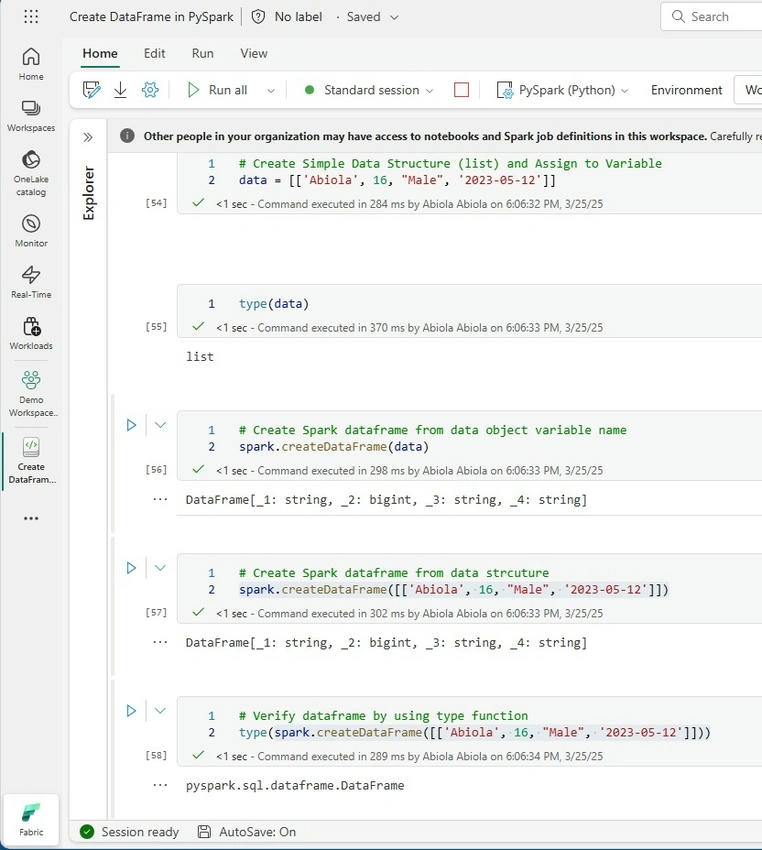
- Create a Simple Data Structure (list) and Assign to a Variable in the Fabric Notebook.
- Display the type of the data structure
- Create a Spark dataframe from the data object variable name
- Create a Spark dataframe from a data structure
- Verify the dataframe by using the type function
To execute all that, I will execute the code seen in the screenshot below.
Next, we want to,
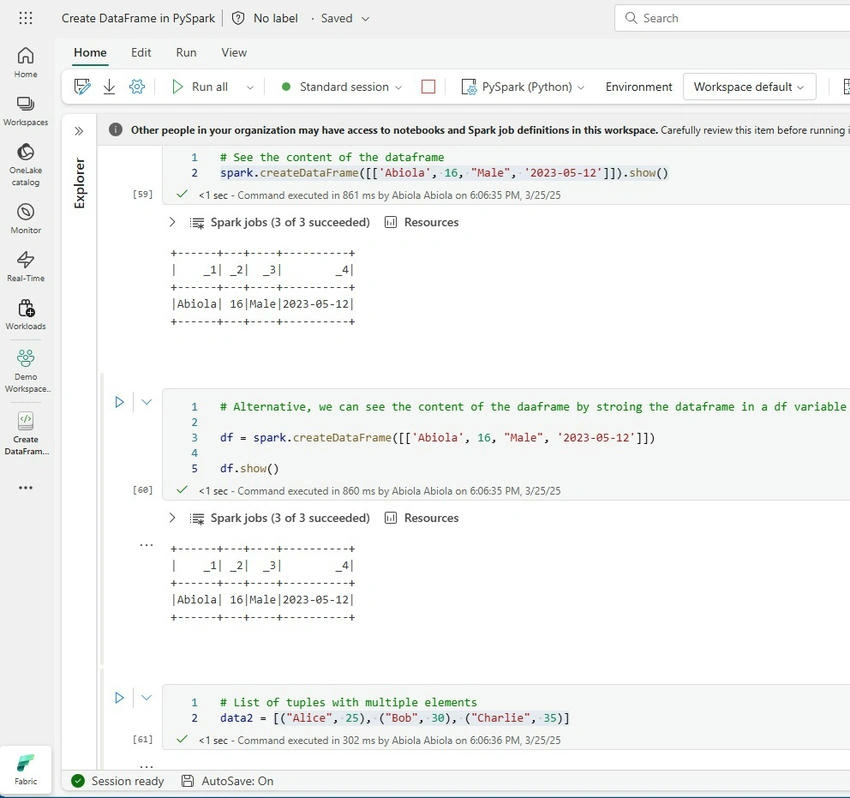
- See the content of the dataframe
- Alternative way to show the content of the dataframe
- List of tuples with multiple elements
To achieve that, I executed the code seen in the screenshot below.
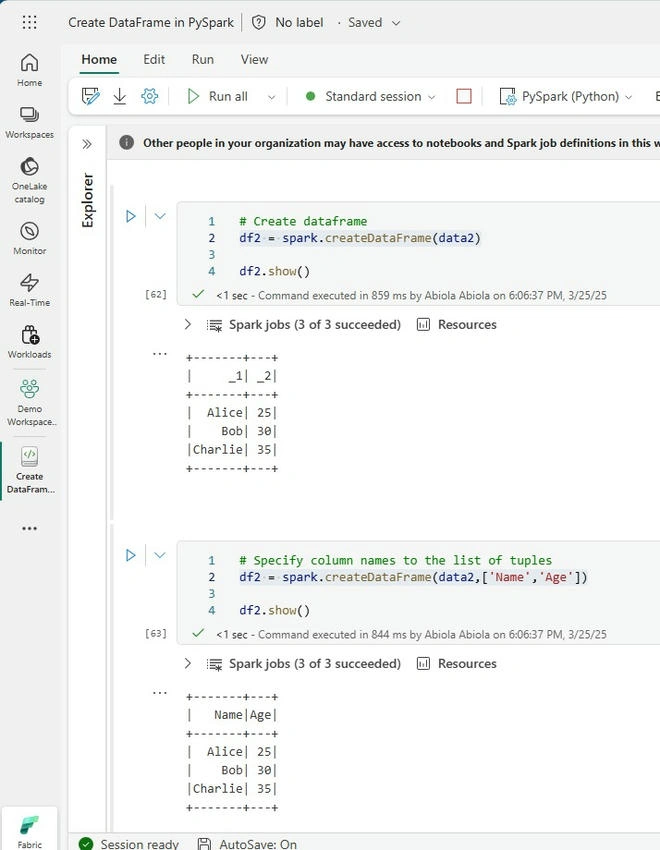
We want to proceed to,
- Create a dataframe using the data2 variable of the tuple list
- Specify column names to the list of tuples
After doing that, we want to,
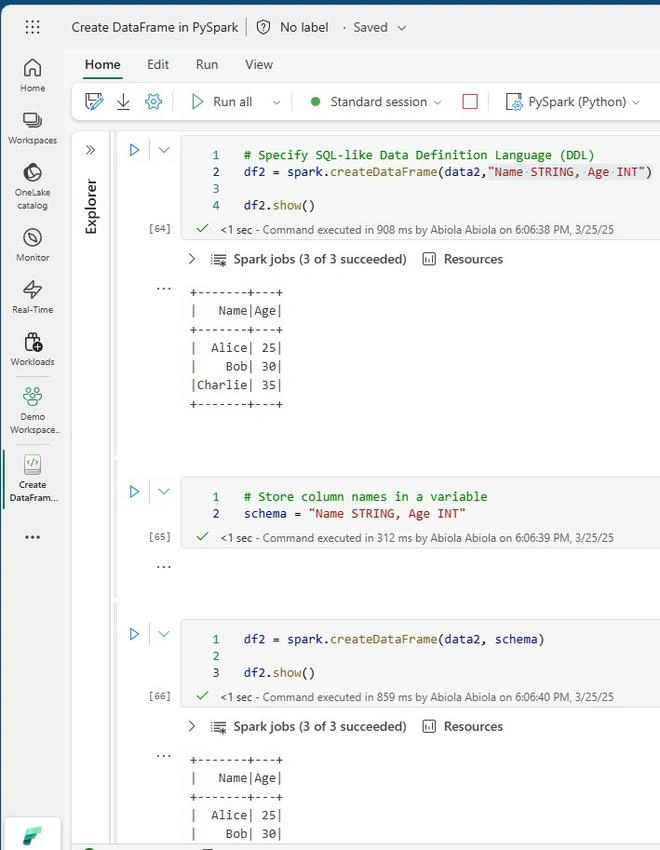
- Specify data types using SQL-like Data Definition Language (DDL)
- Store column names in a variable
- Create another spark dataframe using the data2 and the schema
To achieve that, I executed the code in the screenshot below.
We proceed to,
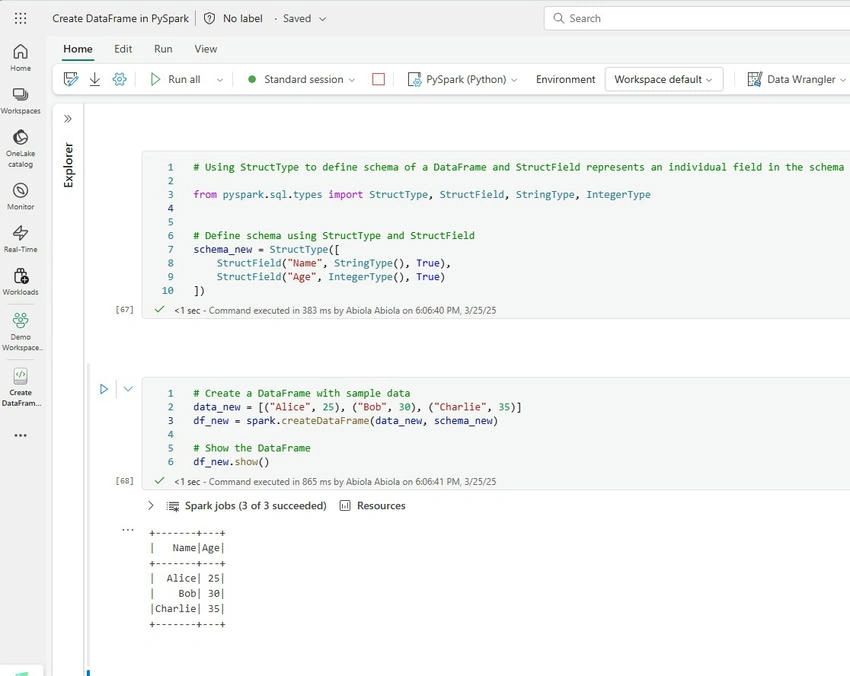
- Use StructType to define the schema of a DataFrame and StructField to represent individual fields in the schema.
- Create another dataframe
- Show the content of the new dataframe
So, the code in the screenshot is executed.
Finally, we proceeded to,
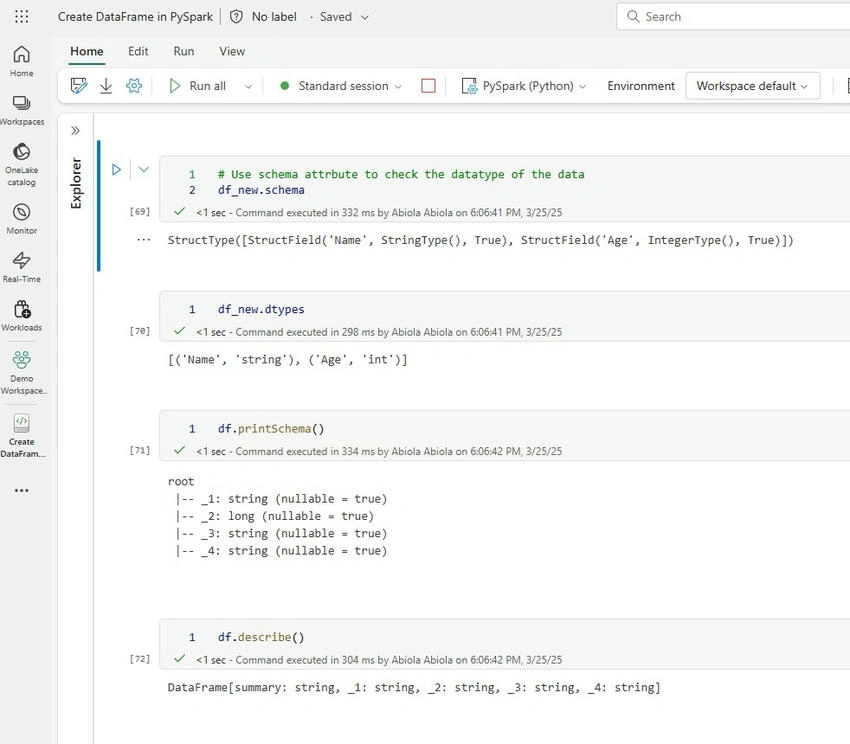
- Useschema attribute to check the datatype of the data
- Describe the dataframe
See you in the next article.
Join the conversation! Your thoughts help the community grow.