
Without a doubt, the Java SDK is the most popular and full featured of the languages supported by Apache Beam and if you bring the power of Java's modern, open-source cousin Kotlin into the fold, you'll find yourself with a wonderful developer experience. As with most great relationships, not everything is perfect, and the Beam-Kotlin one isn't totally exempt.
This post will cover some of the unique interactions between the two technologies and help you avoid some of the potential landmine gotchas that could arise when you are getting started, so you can focus on the great experience between Kotlin and Beam.
Declaring Anonymous ParDos / DoFns
- lines.apply("Extract Words", ParDo.of(new DoFn<String, String>() { ... }));
- lines.apply("Extract Words", ParDo.of(DoFn<String, String>() { ... }))
- lines.apply("Extract Words", ParDo.of(object : DoFn<String, String>() { ... }))
Defining TupleTags
TupleTags can be invaluable and necessary if you are dealing with transforms or operations that deal with multiple types, however you may find that issues bubble up related to the declarations of these that cause you to either explicitly require a Coder to be defined via the setCoder() function after retrieving a specific tag.
A dead giveaway would be the following error,
Exception in thread "main" java.lang.IllegalStateException: Unable to return a default Coder for Transform.out1 [PCollection]. Correct one of the following root causes: No Coder has been manually specified; you may do so using .setCoder(). Inferring a Coder from the CoderRegistry failed: Unable to provide a Coder for V. Building a Coder using a registered CoderProvider failed. See suppressed exceptions for detailed failures. Using the default output Coder from the producing PTransform failed: Unable to provide a Coder for V. Building a Coder using a registered CoderProvider failed.
- val userTag = TupleTag<KV<String, User>>()
- val usersTag = object: TupleTag<KV<String, User>>() {}
The use of the object and trailing open-close curly braces allow the specific types to not be lost when attempting to read from the tag.
IntelliJ Generated Overrides
One of the most appealing features of IntelliJ is the ability to allow the IDE to generate any missing overrides for you when implementing or inheriting from another class / interface. Due to Kotlin’s typechecking system, this can be a challenge since Kotlin explicitly uses a ? character to denote nullability, but Beam will want you to ensure that the types match exactly.
- class ExampleTransform: PTransform<PCollection<KV<String, Test>>, PCollectionTuple>() {
- // Omitted for brevity
- }
You know that you need to perform some type of operation here, so you take advantage of your IDE and allow it to generate the appropriate overrides,
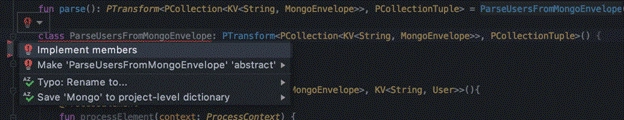
- // Notice the trailing ? after the type definition the input
- override fun expand(input: PCollection<KV<String, Test>>?): PCollectionTuple {
- TODO("Not yet implemented")
- }
- override fun expand(input: PCollection<KV<String, Test>>): PCollectionTuple {
- TODO("Not yet implemented")
- }
Iterables, But Which Ones?
Both Java and Kotlin have notions of an Iterable interface for working with collections of items, however when leveraging them via a grouping/batching operation such as the GroupIntoBatchs transform, a Kotlin-Java JVM disconnect can occur between the types.
.apply("Batch Items", GroupIntoBatches.ofSize<Key, Value>(100))
.apply("Apply Batching Transform", ParDo.of(SomeTransform.transform()))
You may encounter an error that looks like the following,
ProcessContext argument must have type DoFn<Iterable<? extends Value>, Result<? extends Value>>.ProcessContext
- class SomeTransform: DoFn<KV<Key, Iterable<Value>>, KV<Key, Value>>(){
- // Omitted for brevity
- }
- class SomeTransform: DoFn<KV<Key, Iterable<@JvmWildcard Value>>, KV<Key, Value>>(){
- // Omitted for brevity
- }
This hint to the JVM should allow it to determine the correct version of the interface to use and be serialized/deserialized by the Beam programming model.
Writing Pipeline Tests
Testing, particularly unit testing, is extremely important when writing Beam applications (and obviously always), however there are two major gotchas in the testing department that you should be aware of when working with Kotlin, namely,
- Defining Your Pipeline
- Apply PAsserts
- Running Pipeline Tests
Defining Your Pipeline
- @get:Rule
- @Transitive
- val testPipeline: TestPipeline = TestPipeline.create()
All of your individual unit tests can share this pipeline, but you should consider writing it exactly as above since both the @get:Rule and @Transitive annotations are required, as is the explicit type declaration (e.g. : TestPipeline).
Applying PAsserts
- PAssert.that(numbers).satisfies { elements ->
- assertTrue(elements.contains(42))
- }
- PAssert.that(numbers).satisfies { elements ->
- assertTrue(elements.contains(42))
- null // Required
- }
Running Pipeline Tests
- PAssert.that(numbers).containsInAnyOrder(42)
- testPipeline.run().waitUntilFinish()
Since the PAssert is constructed as part of the dynamic acyclic graph that executes the pipeline, it must be declared prior to running the tests. You’ll also find that you won’t be able to debug any of the ParDo level operations if you are missing the run() declaration.
Missing a Gotcha?
Join the conversation! Your thoughts help the community grow.